Top 10 AI Tools for Developers 2026: Features, Pricing, and Best Use Cases
AI coding tools have moved far beyond simple autocomplete. In 2026, developers can use AI to understand entire codebases, generate and edit files, debug applications, write tests, refactor projects, run commands, and even complete software tasks with limited supervision. With so many options available, choosing the right tool can be difficult. Some are built for everyday coding and autocomplete, while others focus on autonomous agents, large codebases, enterprise security, or rapid application development. This guide covers the top AI tools for developers 2026, including key features, pricing, strengths, and ideal use cases, so you can pick the best AI developer tools for your workflow. Why AI Tools for Developers 2026 Matter AI has become a core part of the modern software development workflow. Developers now use AI assistants for tasks such as: The biggest change is the shift from assistants that simply suggest code to AI agents that can perform multi-step development tasks. Tools such as Cursor, Claude Code, GitHub Copilot, and Devin can work across multiple files and handle work that once required significant manual effort. However, the best tool depends on your development environment, budget, preferred workflow, and the level of control you want over AI-generated code. 1. GitHub Copilot What Is GitHub Copilot? GitHub Copilot is one of the most established AI coding assistants. It integrates directly with popular development environments and GitHub, helping developers write, review, explain, and modify code. It supports code completion, chat, coding agents, CLI workflows, and code review. Key Features GitHub has also moved Copilot toward usage-based billing through AI Credits. Paid plans currently start at $10 per user per month, while Business and Enterprise plans start at $19 and $39 per user per month respectively. Best For GitHub Copilot is a strong choice for developers and teams that already use GitHub heavily and want coding assistance built into their existing workflow. Pricing: Free tier available. Paid plans start at approximately $10/month for individuals. 2. Cursor What Is Cursor? Cursor is an AI-first code editor based on Visual Studio Code. Instead of treating AI as an extra extension, Cursor puts it at the center of the development experience. Its agent capabilities can understand project context, edit multiple files, refactor code, and help implement features. Key Features Cursor is especially interesting for developers in India because it introduced Cursor Start at ₹649/month, with access to Cursor models, Composer, cloud agents, and other features. Its Pro plan starts at $20/month. Best For Cursor is perfect for those who frequently work on projects that require multi-file modifications or refactoring and who desire an AI-native coding environment. Pricing: Free tier available. Cursor Start in India is ₹649/month, while Pro starts at $20/month. 3. Claude Code What Is Claude Code? For developers that want AI to interact directly with their repositories and development environments, Anthropic offers an agentic coding tool called Claude Code. Instead of only suggesting the next line, it can analyze a project, make changes across multiple files, run commands, execute tests, and help complete larger tasks. Key Features Best For Files that are extremely helpful code code code code code code code code code are unfamiliar to Claude. It is also helpful for complex refactoring, debugging, testing, and AI/ML development workflows. Pricing: Subscription and API-based options are available. Pricing varies by plan and model usage. 4. ChatGPT for Coding and Codex What Is Codex? Codex is OpenAI’s coding agent for software development. It can help developers write, review, modify, and ship code. Codex is integrated into ChatGPT and is also available through developer-focused workflows. It is designed for longer tasks where the AI works through multiple steps rather than just answering a programming question. Key Features Codex is included throughout ChatGPT plans, including Free and Go, although usage limits differ per plan. Best For ChatGPT for coding is a good choice for developers who already use ChatGPT for planning, documentation, research, and technical problem-solving and want coding capabilities in the same ecosystem. Pricing: Codex is included with ChatGPT plans. Higher usage is available through paid plans and applicable credit or usage-based options. 5. Gemini Code Assist What Is Gemini Code Assist? Gemini Code Assist is Google’s AI coding helper for developers. It provides agentic development capabilities across supported environments, conversational assistance, and coding recommendations.It is especially attractive for teams already working with Google Cloud. Key Features One important change in 2026 is that Google’s consumer version of Gemini Code Assist was deprecated. Starting June 18, 2026, the consumer IDE extensions and Gemini CLI stopped serving requests, while Standard and Enterprise subscriptions remain available. Best For Gemini Code Assist is best suited to developers and organizations already using Google Cloud or other Google development services. Pricing: Standard and Enterprise plans are available. Consumer access changed significantly in 2026, so check Google’s current plans before subscribing. 6. Cline What Is Cline? Cline is an open-source AI coding agent that works inside your development environment. It can interface with external external project project terminal tools. One of its biggest advantages is flexibility, since developers can connect it to different AI model providers instead of being locked into one model. Key Features Best For Cline is a good option for developers who want more control over their AI coding workflow and prefer choosing their own model provider. Pricing: The core tool is free and open source. You pay separately for the AI model or API usage you connect to it. 7. Aider What Is Aider? Aider is an open-source AI pair-programming tool for developers who prefer working from the command line. It works directly with Git repositories and can modify existing code based on natural-language instructions. Key Features Best For Aider is particularly useful for developers who are comfortable in the terminal and want a lightweight, open-source alternative to AI-native code editors. Pricing: Free and open source. Model and API costs are charged separately. 8. Tabnine What Is Tabnine? Tabnine is an AI coding platform focused heavily on enterprise development and data privacy. Unlike many tools that
What Is SailPoint? A Beginner’s Guide to Identity Governance
Every employee, contractor, bot, and application in your company holds a key to something. Multiply that across thousands of users and hundreds of systems, and nobody can say with confidence who can access what. That gap is where breaches, failed audits, and costly mistakes begin. So, what is SailPoint? SailPoint is an enterprise identity security platform that controls who has access to which applications, data, and systems, and proves that the access is appropriate. It is the name most associated with identity governance, and one of the most in-demand skills in IAM today. In this guide, you will learn what SailPoint does, how its products differ, what a SailPoint IIQ tutorial should cover, what the career path pays, and how to start learning. What Is SailPoint? Definition and Overview SailPoint is an identity governance and administration (IGA) platform that automates how organizations grant, review, and remove user access. In plain terms, it answers three questions: Who has access? Should they have it? Can you prove it? SailPoint was founded in 2005 in Austin, Texas. Thoma Bravo acquired the company in 2022, and SailPoint returned to the public markets with a Nasdaq listing in 2025. Large banks, healthcare systems, retailers, and government agencies use it to manage millions of identities. You can explore the vendor’s own overview on the official SailPoint website. Why does it matter now? Cloud adoption, remote work, and AI-driven attacks have made stolen or excessive access the easiest way into a company. Analyst firms such as Gartner consistently place IGA at the center of modern identity strategy, and SailPoint is regularly named among its leaders. Why Identity Governance Matters Identity governance is the practice of managing digital identities and their access rights throughout their lifecycle, so the right people have the right access at the right time. Think of it like building security. A visitor badge should expire, a manager’s badge should open more doors than an intern’s, and someone should check the badge list regularly. Identity governance does this for your digital systems. Without it, three problems appear quickly: Here is a common scenario. An employee resigns on Friday, but her HR record is updated Wednesday, and her access to the finance application is never removed. Three months later, her credentials are used in an attack. SailPoint prevents this by tying access directly to the HR source and removing it automatically. Key SailPoint Products Explained SailPoint offers one core product family in different deployment models. Here is how they relate. SailPoint IdentityIQ (IIQ) IdentityIQ is the self-hosted, on-premise (or private cloud) platform. It is highly customizable, which is why large enterprises with complex legacy systems still rely on it. Most SailPoint developer jobs today still involve IIQ. SailPoint IdentityNow IdentityNow is the cloud-based SaaS version. SailPoint hosts and updates it, so customers spend less time on infrastructure and upgrades. SailPoint Identity Security Cloud Identity Security Cloud is the evolution of IdentityNow. It adds AI-driven recommendations, access modeling, and broader coverage of non-human and machine identities. IIQ vs. IdentityNow at a Glance Feature SailPoint IIQ SailPoint IdentityNow / Identity Security Cloud Deployment On-premise or private cloud Cloud SaaS Customization Very high (Java, BeanShell rules) Moderate (configuration, APIs, transforms) Maintenance Customer-managed SailPoint-managed Typical user Large, complex enterprises Cloud-first and mid-to-large organizations Skills needed Java, XML, SQL APIs, JSON, scripting Core Features and Capabilities SailPoint’s core features cover the full identity lifecycle, from the day someone joins to the day they leave. SailPoint IIQ Tutorial: A Beginner’s Starting Point SailPoint IdentityIQ is an on-premise identity governance platform used mainly by large enterprises to automate access, certifications, and compliance. Banks, insurers, healthcare providers, and global consultancies are typical users. This SailPoint IIQ tutorial introduction focuses on four concepts you will meet in every project: Picture a new hire. HR data triggers a task, a rule calculates the username, a workflow requests approvals, and a connector creates the account. Once you understand that chain, most of IIQ makes sense. To go beyond concepts, hands-on practice matters most. A structured SailPoint Training Course gives you lab environments, guided exercises, and real project scenarios, which are hard to build on your own. SailPoint Career Opportunities: Jobs, Salaries, and Growth SailPoint career opportunities are strong because every large organization needs identity governance, and certified professionals are still scarce. In-demand roles include: Approximate 2025-2026 salary ranges (varying by city, employer, and experience): Role level United States (annual) India (annual) Entry-level / Analyst $75,000 – $95,000 ₹4 – 8 LPA Mid-level Developer / Consultant $110,000 – $140,000 ₹12 – 25 LPA Senior / Architect $150,000 – $190,000+ ₹30 – 45 LPA Why is this future-proof? Regulations keep tightening, and companies keep adding cloud apps, contractors, and machine identities. Each one needs governing. Automation will change the work, but it increases the need for people who can design and troubleshoot identity programs. Employers also struggle to find job-ready talent. That is the gap Akira’s IT staffing and corporate training services help close, connecting trained professionals with companies that need them. How to Learn SailPoint: A Beginner’s Roadmap The fastest way to learn SailPoint is to build IAM fundamentals first, then move into IIQ or IdentityNow with hands-on labs. Prerequisites (helpful, not all mandatory): basic IT knowledge, Java fundamentals, SQL, and networking basics. Your learning path: Akira’s SailPoint Training Course follows this path with live instructor-led classes, real projects, and placement support. If you are targeting integration-heavy roles, adding CRM knowledge helps. Many companies connect identity platforms to Salesforce, so our Salesforce Training Course is a useful complementary skill. You may also explore ServiceNow and CyberArk courses, which pair naturally with IAM careers. Why Choose Akira Global Technologies for SailPoint Training? Akira Global Technologies is built around one outcome: getting you job-ready. Here is what you can expect: Whether you are a fresh graduate or switching careers, you get guidance from people who work with these technologies daily. Conclusion: Start Your Identity Governance Journey So, what is SailPoint? It is the identity governance platform that helps enterprises
What is Apache Spark? Beginner’s Guide with Real-World Use Cases
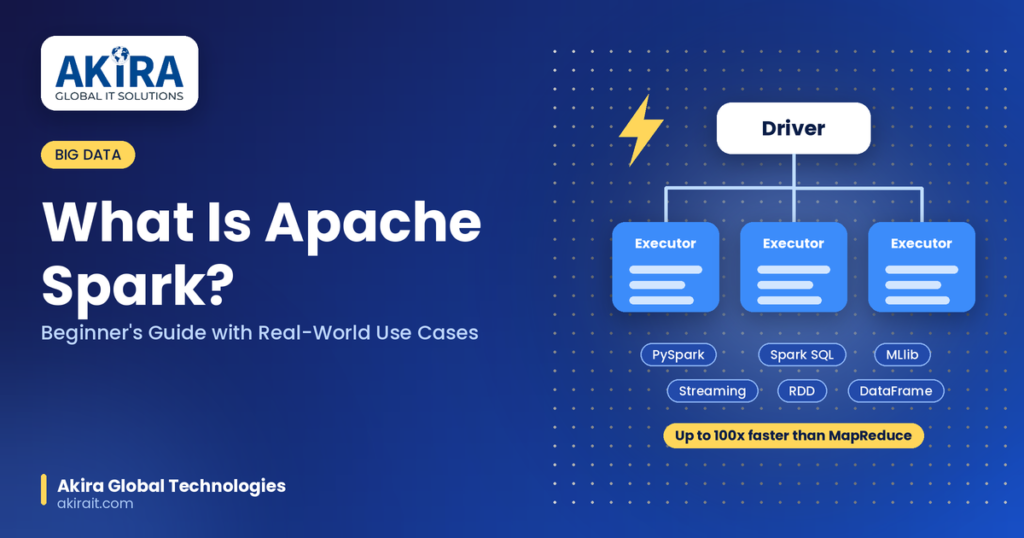
If you are exploring big data, data science, or data engineering, you will meet Apache Spark very quickly. So, what is Apache Spark, and why do so many companies rely on it? Spark powers fraud detection at banks, recommendation engines on streaming platforms, and analytics pipelines at some of the biggest organizations in the world. This Apache Spark tutorial explains everything in simple language. You will learn how Spark works, what its architecture looks like, how Spark vs Hadoop compares, how to start with PySpark for beginners, and where Spark is used in real life. If you want to turn this knowledge into a career, a structured Data Engineering course can help you go deeper. What is Apache Spark? Apache Spark is an open-source, distributed computing framework built for large-scale data processing and analytics. “Open-source” means anyone can use it for free. “Distributed” means the work is shared across many computers instead of one. Spark began at UC Berkeley’s AMPLab in 2009. It was later donated to the Apache Software Foundation and became a top-level Apache project in 2014. Today it is one of the most popular big data tools in the world. Here is the basic idea. Spark takes a huge dataset, splits it into smaller pieces, and spreads those pieces across a cluster of machines. Each machine works on its own piece at the same time, and Spark combines the results at the end. What makes Spark special is speed. Older systems save data to disk after every step, which is slow. Spark keeps most of its data in memory (RAM), so it can finish certain jobs up to 100 times faster than Hadoop MapReduce. Spark also supports Python, Scala, Java, and R, so people from different backgrounds can use it. A Simple Way to Think About Spark Imagine you need to count the words in 1,000 books. If one person reads all of them, it takes weeks. If 100 people each read 10 books and then add up their counts, it takes a day or two. Spark works the same way. The “driver” is the manager who hands out the books, the “executors” are the readers, and the final count is the combined result. Keep this picture in mind, because it makes the architecture section below much easier. Why Apache Spark Matters in Big Data Processing Businesses create data every second: website clicks, app activity, payments, and sensor readings from connected devices. Traditional tools struggle with this volume, speed, and variety. Spark solves these problems in several ways: Because of these strengths, Spark is now a core skill for data engineers, data analysts, and machine learning engineers. Apache Spark Architecture Explained To understand how Spark works, you need to know its main building blocks. 1. Driver Program The driver is the brain of every Spark application. It runs your main function, creates the SparkContext, and plans how work is divided across the cluster. 2. Cluster Manager The cluster manager decides which resources each application gets. Spark works with its own standalone manager, Hadoop YARN, Apache Mesos, and Kubernetes. 3. Executors Executors are worker processes running on the cluster nodes. They carry out the tasks given by the driver and store data in memory or on disk. 4. Resilient Distributed Datasets (RDDs) An RDD is Spark’s basic data structure. It is an immutable (unchangeable), distributed collection of objects that can be processed in parallel. If a piece of data is lost because a node fails, Spark rebuilds it using lineage information, which is a record of how the data was created. 5. DataFrames and Datasets RDDs are powerful but can be hard to write. DataFrames are easier because they work like tables with named columns, and Spark’s Catalyst optimizer makes their queries run faster. Datasets add type safety on top of those optimizations. Core Spark Modules Spark vs Hadoop: What Is the Difference? Beginners often ask about Spark vs Hadoop, because both are well-known big data frameworks. The fair comparison is Spark against Hadoop MapReduce, which is Hadoop’s processing engine. Feature Apache Spark Hadoop MapReduce Processing speed Up to 100x faster (in-memory) Slower (disk-based) Ease of use High-level APIs, multiple languages Complex, mainly Java Real-time processing Yes, via Structured Streaming No, batch only Machine learning Built-in MLlib Needs external libraries Fault tolerance Yes, via RDD lineage Yes, via data replication MapReduce laid the foundation for distributed data processing. But when a company needs speed, real-time analytics, and built-in machine learning, Spark is usually the better pick. In the Spark vs Hadoop discussion, it is not always a choice of one or the other. Many organizations store data in Hadoop’s HDFS and run Spark on top as the processing engine. The two work well together. Real-World Use Cases of Apache Spark Spark is not just theory. Large companies use it every day to solve business problems. Here are the most common examples. 1. E-commerce and Retail Analytics Online stores process clickstream data to understand what customers like. This helps them personalize recommendations, set better prices, and improve sales. 2. Fraud Detection in Banking and Finance Banks use Spark’s streaming and machine learning features to check transactions as they happen. Suspicious activity gets flagged in milliseconds, before serious damage is done. 3. Recommendation Engines Streaming platforms and online marketplaces use MLlib to build collaborative filtering models. These models study user behavior to suggest movies, songs, or products you are likely to enjoy. 4. Healthcare and Genomics Researchers use Spark to analyze genomic data, patient records, and clinical trial results. These tasks would be too slow and too large for traditional systems. 5. Log Processing and IT Monitoring IT teams process server and application logs in real time. This helps them detect problems early and respond to incidents faster. 6. Social Media and Sentiment Analysis Companies analyze millions of posts and comments to track brand mentions, trending topics, and public opinion. 7. Transportation and Logistics Ride-sharing and delivery companies use Spark to plan routes, predict demand, and manage live fleet
IT Training vs College Degree: What’s Better for Getting a Tech Job?
You finished school or college, and now everyone has advice. One relative says you need a B.Tech or MCA. A friend swears a three-month course got him a job at a startup. A YouTube video says degrees are dead. So which one is true? If you are a fresher or a career switcher in India, this confusion is real, and it can cost you months or even lakhs of rupees. The question of IT training vs college degree is not about which option is good and which is bad. It is about which one fits your age, budget, goals, and timeline. In this guide, you will see what each path really offers, where each one falls short, and what recruiters in Indian companies actually check. You will also get a simple step-by-step plan for 2026. By the end, you should know which direction makes sense for you, and what to do in the next 30 days. Why This Debate Matters More Than Ever Ten years ago, the path was simple. You took a degree, you sat for campus placements, and you joined a service company. That path still works for many people, but it is no longer the only one. Today, thousands of engineering graduates compete for the same entry-level roles every year. Many of them struggle to clear technical interviews because their practical skills are thin. At the same time, companies are asking for job-ready candidates who can contribute in weeks, not months. ‘Meanwhile, tools like cloud platforms, AI assistants, and DevOps pipelines change quickly. A syllabus written four years ago may not cover them. This gap is why so many people are asking whether a technical training program can do what a classroom degree sometimes cannot.’Meanwhile, tools like cloud platforms, AI assistants, and DevOps pipelines change quickly. A syllabus written four years ago may not cover them. This gap is why so many people are asking whether a technical training program can do what a classroom degree sometimes cannot. Your choice affects your salary, your confidence, and your first five years of career growth. It deserves a clear-headed look. What a College Degree Offers A degree such as B.Tech, BCA, B.Sc. Computer Science, or MCA is still the most recognised credential in India. It gives you a structured, long-term foundation. But it also comes with limits you should know about. Strengths of a Traditional Degree A computer science degree teaches you the theory behind the tools: data structures, algorithms, operating systems, databases, and networks. This foundation helps you later when you move into system design, research, or senior engineering roles. A degree also opens doors that are closed otherwise. Many large service companies, government jobs, PSUs, and higher studies like M.Tech or MBA require one. If you want to study abroad, a degree is usually mandatory. Finally, campus life gives you networking, peer learning, and sometimes on-campus placements. In tier-1 colleges, the placement record can be excellent, with fresher packages from ₹6 to ₹20 lakh per year or more. Where Degrees Fall Short The biggest problem is the gap between syllabus and industry. Many colleges, especially in tier-2 and tier-3 cities, still teach outdated tools and focus heavily on exams rather than projects. Time and cost are also factors. A four-year engineering degree can cost anywhere from ₹2 lakh in a government college to ₹15 lakh or more in a private one. That is a big investment, and there is no guarantee of a job at the end. Placement quality also varies widely. A graduate from a weak campus may get no offers at all, even with good marks. What IT Training and Bootcamps Offer IT training programs and bootcamps take a different approach. They skip most theory and focus on what employers need on day one. Here is what that looks like in practice. Strengths of IT Training The biggest advantage is speed. Most programs run from three to eight months, so you can start applying for jobs much sooner. The cost is also lower, usually between ₹30,000 and ₹1.5 lakh. Hands-on training is the core of these courses. You build real projects, use real tools, and learn the way teams actually work. Good career-ready IT training programs also include mock interviews, resume support, and placement support, which many degree colleges lack. An IT certification alongside training, such as AWS, Azure, or Oracle, adds proof of skill. It also helps your resume pass automated filters. Limitations to Consider Not all training providers are equal. Some sell glossy promises and deliver weak teaching. You must check trainer experience, project quality, and real placement records before you pay. Training also does not replace a degree in every situation. Some employers, especially large multinationals and government bodies, still list a degree as a minimum requirement. Short courses can also leave gaps in computer science basics, which you may need to fill through self-study later. IT Training vs College Degree: A Side-by-Side Comparison Here is a simple view of how the two paths compare for most learners in India. Factor College Degree IT Training / Bootcamp Cost ₹2 lakh to ₹15 lakh+ ₹30,000 to ₹1.5 lakh Duration 3 to 4 years 3 to 8 months Curriculum Broad, theory-heavy, updated slowly Narrow, skill-focused, updated often Hands-on projects Limited, varies by college Core part of the course Placement support Strong in top colleges, weak elsewhere Usually included, quality varies Industry recognition Very high, widely accepted Growing, depends on provider and portfolio The table shows a clear pattern. A degree gives you depth and recognition, while training gives you speed and practical skill. Neither wins on every row, which is why many smart candidates combine both. Online IT Courses vs Degree: Which Fits Your Situation? The online IT courses vs degree question depends mostly on where you are in life. If you are 18 or 19 and just finished Class 12, a degree is usually the safer base. You have time, and the structure helps. You can add an online course or certification
.NET Full Stack Developer Career: Salary, Skills and Roadmap for 2026
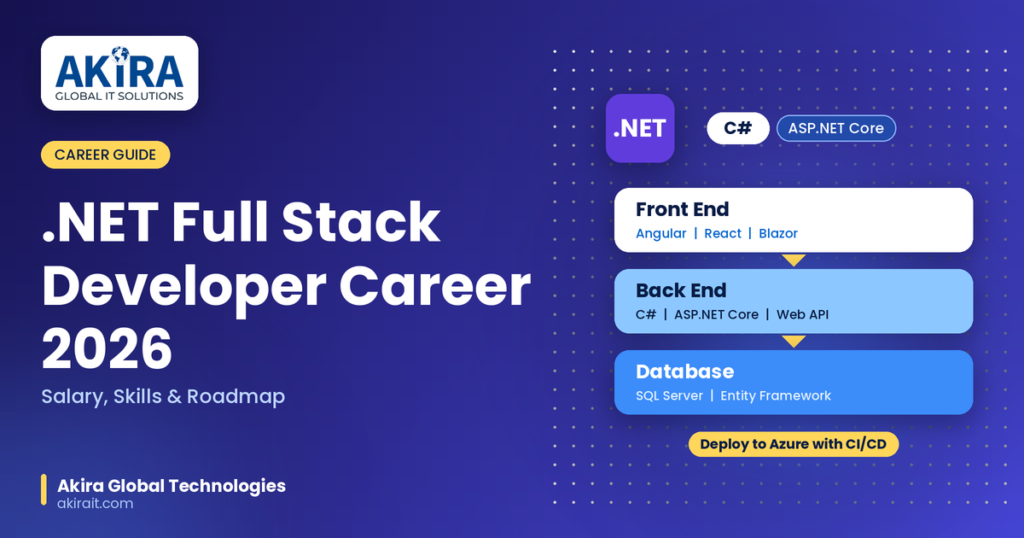
Look at what companies want from developers today and one pattern stands out. They want people who can own an application end to end, from the button a user clicks to the last row in the database. That is exactly why a .NET Full Stack Developer career is one of the most stable and well-paying paths in tech right now. Whether you are a fresher, a student, or an experienced developer switching stacks, this guide gives you a clear picture. You will learn what to study, how much you can earn, which roles to aim for, and where the field is heading. By the end, you will also have a practical, step-by-step plan you can start following this week. What Does a .NET Full Stack Developer Do? A .NET Full Stack Developer works on both sides of a web application. On the back end, they use C# and ASP.NET Core to build APIs, business logic and data access layers. On the front end, they create user interfaces with Angular, React or Blazor. In between, they handle database design, authentication, security and cloud deployment. A typical week might include building a new REST API endpoint on Monday, fixing a UI bug on Tuesday, optimizing a slow SQL query on Wednesday, reviewing a teammate’s pull request on Thursday, and deploying a release to Azure on Friday. That variety is a big part of the appeal. For employers, the benefit is simple. One skilled developer can handle multiple layers of a project, so delivery is faster and team coordination is easier. This is why startups and large enterprises alike value full stack profiles. Why Build a Career in .NET Full Stack Development? There are several practical reasons why this path keeps attracting new talent: Core Skills You Need To build a successful .NET Full Stack Developer career, you need a balanced mix of front end, back end, database and cloud skills. Front End Skills Back End Skills Database Skills Cloud and DevOps Skills Soft Skills A debugging mindset, clear communication and comfort working in Agile teams matter more than most beginners expect. In interviews, these skills often decide between two equally strong candidates. Full Stack .NET Roadmap: Step by Step Learning everything at once is the fastest way to burn out, which is why a structured .NET developer course can save you months of trial and error. This Full Stack .NET roadmap is arranged in a practical order, so each step builds on the previous one. With consistent practice, most learners become job-ready in 8 to 12 months. If you already know another programming language, you can often shorten that timeline. ASP.NET Core Tutorial: Where to Start If you are looking for an ASP.NET Core tutorial, the best approach is to build a small API from scratch rather than just reading documentation. Here is a simple sequence to follow: This short flow gives you a hands-on feel for routing, dependency injection and data access. That is the real goal of any ASP.NET Core tutorial: less reading, more building. Once you finish this mini project, try extending it with pagination, logging and unit tests. Those extras are what separate a tutorial project from a portfolio project. .NET Developer Salary in 2026 The .NET developer salary depends on experience, city, company size and skill stack. The ranges below are approximate and based on market trends, so verify current data when you are evaluating an offer. India (per annum) Level Experience Approx. Salary Entry 0 to 2 years ₹4 to 7 LPA Mid 3 to 6 years ₹8 to 15 LPA Senior 7+ years ₹16 to 30 LPA+ United States (per year) Level Approx. Salary Entry $70,000 to $90,000 Mid $95,000 to $130,000 Senior $135,000 to $170,000 Metro cities such as Bengaluru, Hyderabad, Pune and Mumbai usually pay higher than smaller cities, though remote roles are narrowing that gap. Product companies and well-funded startups tend to pay more than service companies at the same experience level. Factors that push your .NET developer salary higher: Job Roles on This Path A strong .NET Full Stack Developer career can lead to a wide range of roles: Most people start as a junior developer, move to a senior role within four to six years, and then choose between a technical track (architect) and a management track (engineering manager). Certifications Worth Considering A good .NET certification course will not replace real experience, but it helps your resume get noticed. These are worth considering: Recruiters give more weight to real projects than to certificates, so treat certifications as a supplement. How to Land Your First .NET Job Getting the first job is usually the hardest part. These steps make it easier: Common Mistakes to Avoid Future Scope of .NET Full Stack Development The outlook remains positive for several reasons: Developers who keep learning, especially cloud and AI-related skills, will stay in demand for years. Tips to Grow Faster Conclusion A .NET Full Stack Developer career offers a rare mix of technical growth, good pay and long-term stability. The path is clear: start with C#, build depth in ASP.NET Core and a front end framework, then add databases and Azure. The one rule that matters most is to keep building projects as you learn. If you want structured guidance or industry-level project experience, connect with Akira Global Technologies and give your .NET career the right direction. Frequently Asked Questions 1. What is the average .NET developer salary in India? Entry-level developers typically earn ₹4 to ₹7 LPA. Senior professionals can reach ₹16 to ₹30 LPA or more, depending on skills and company. 2. What skills are required for a .NET Full Stack Developer career? C#, ASP.NET Core, Entity Framework Core, SQL Server, a front end framework (Angular or React) and basic Azure knowledge. 3. Is .NET full stack a good career in 2026? Yes. Demand for .NET remains steady in enterprise, cloud and microservices projects, and full stack profiles have an edge in hiring. 4. How long does it take to
Machine Learning Roadmap: From Beginner to Job-Ready in 6 Months
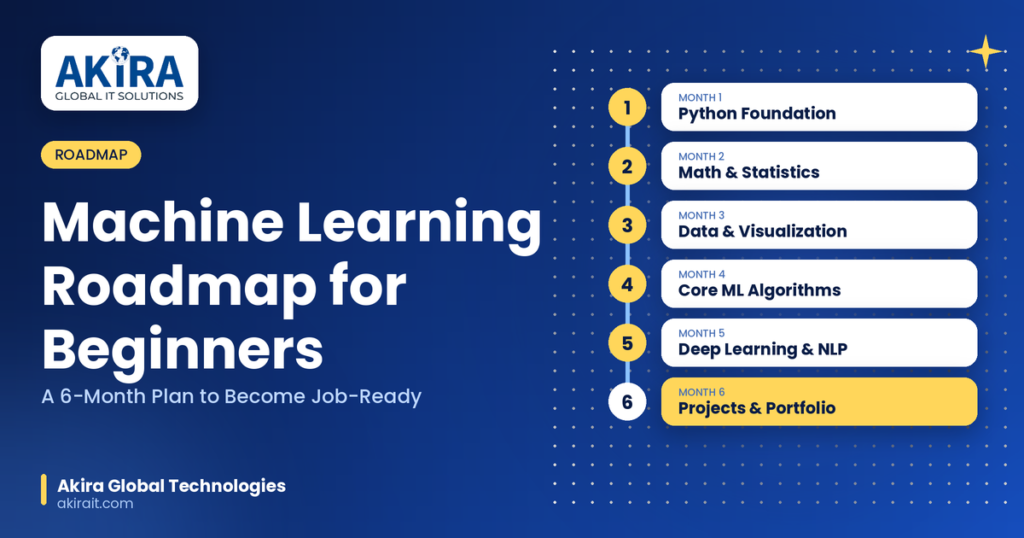
Artificial intelligence is changing how every industry works, and the demand for people who understand it is growing fast. If you have ever wondered how to enter this field without a technical background or years of experience, you are in the right place. The good news is that with the right plan, consistent practice, and a clear direction, you can become job-ready in just six months. In this guide, you will find a complete machine learning roadmap for beginners, broken down month by month. Each stage tells you what to learn, which tools to use, and what to build, so you always know your next step. Whether you are a student, a working professional, or someone planning a career switch, this AI learning roadmap 2026 will help you move forward with confidence. Introduction: Why You Need a Machine Learning Roadmap for Beginners Machine learning powers the recommendations you see on streaming apps, the fraud alerts from your bank, and the chatbots that answer customer questions. Many people want to learn machine learning, but they get stuck because the field feels huge and unstructured. That is exactly why a clear machine learning roadmap for beginners matters. Without a plan, learners jump between random tutorials, start with advanced neural networks before understanding basic Python, and lose motivation. A structured roadmap fixes this by showing what to learn, in what order, and for how long. Why 2026 Is a Great Time to Start If you are considering an ML career path, 2026 is an excellent moment. Companies in healthcare, finance, retail, manufacturing, and education are adopting AI at scale, and demand for people who can build and deploy models keeps growing. Beginner-friendly tools, free datasets, and cloud platforms have also made it easier than ever to practice. This AI learning roadmap 2026 is designed to take you from zero to job-ready in six months, assuming about 10 to 15 hours of study per week. Here is the plan at a glance: Month 1: Python Programming Foundation Python is the most popular language in AI and machine learning because it is readable, beginner-friendly, and backed by a massive ecosystem of libraries. Every step of this machine learning roadmap for beginners depends on it, so do not rush this month. What to Learn Practical Tip Solve small problems daily, such as a number guessing game, a to-do list app, or a text file word counter. If you prefer guided learning with mentorship, a structured python developer course can help you build strong fundamentals quickly. Learners who also want hands-on industry exposure may like a python course with an internship, which adds real project experience to your resume early. Month 1 goal: Write 100 to 150 lines of clean Python code on your own without copying. Month 2: Mathematics and Statistics for the ML Career Path Many beginners fear this month, but you do not need a math degree. You need to understand the core ideas well enough to know what your models are actually doing. Math is what separates someone who runs code from someone who can debug and improve a model, which is crucial on any ML career path. Linear Algebra Data in machine learning is stored as vectors and matrices. Focus on: These concepts power everything from image processing to recommendation systems. Calculus Calculus explains how models learn. Focus on: Gradient descent is the engine behind model training. If you understand it, you understand how a model improves with each step. Probability and Statistics Statistics helps you understand data and judge results. Focus on: Practical Tip Use visual resources and apply each concept in Python. For example, plot a normal distribution or code gradient descent for a simple function. This keeps the math connected to your machine learning roadmap for beginners rather than feeling abstract. Month 2 goal: Explain gradient descent and Bayes’ theorem in plain language. Month 3: Data Handling and Visualization Real-world data is messy. Data scientists often spend most of their time cleaning and understanding data before modeling. This month teaches the skills you will use every working day. Core Libraries Data Cleaning Practice these tasks on real datasets: Exploratory Data Analysis (EDA) EDA is the process of understanding your data before building a model. Ask questions like: What is the distribution of each feature? Which variables are correlated? Are there unusual patterns? A good EDA often reveals insights that make your model far more accurate. Pick a dataset from Kaggle or the UCI Machine Learning Repository and perform a complete EDA. If you want to extend your skills toward building data-driven web applications, a full stack python course can complement this stage nicely. Month 3 goal: Complete two full EDA notebooks on different datasets. Month 4: Core Machine Learning Algorithms Now the real fun begins. This is where you start to truly learn machine learning by training models on data. Supervised vs. Unsupervised Learning Introduction to Scikit-Learn Scikit-Learn is the go-to library for classical machine learning. It offers a consistent workflow: split your data, fit a model, predict, and evaluate. Algorithms to Master Model Evaluation Learn these concepts early, since they matter in every interview: If you want expert guidance, structured Machine Learning Training can help you practice these algorithms with real datasets and mentor feedback. Month 4 goal: Build three end-to-end models: one regression, one classification, and one clustering project. Month 5: Advanced Topics and Deep Learning With classical ML mastered, you are ready for the next level of this AI learning roadmap 2026: deep learning. Neural Networks Start with the basics: neurons, layers, activation functions (ReLU, sigmoid, softmax), loss functions, and backpropagation. Understand how a network learns by adjusting weights, which connects directly to the calculus you studied in Month 2. TensorFlow or PyTorch Pick one framework and stick with it long enough to build confidence. Build a simple image classifier, such as digit recognition with the MNIST dataset, and then explore Convolutional Neural Networks (CNNs) for images. NLP Basics Natural Language Processing teaches machines to
Spring Boot vs Node.js: Which Backend Framework Should You Learn?
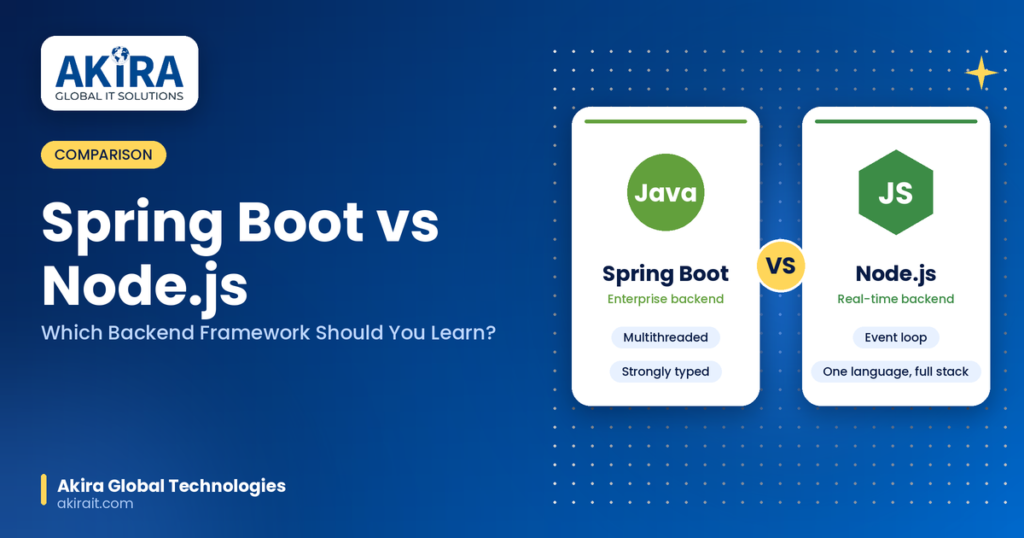
Choosing between Spring Boot vs Node.js can feel like a make-or-break decision when you’re selecting your first (or next) backend framework. Two names dominate almost every “backend roadmap” discussion: Spring Boot, the Java-based enterprise powerhouse, and Node.js, the JavaScript runtime that turned frontend developers into full-stack engineers overnight. Both are excellent, both are in high demand, and both can build the same kinds of applications – but they take very different paths to get there. This guide breaks down everything you need to know to make an informed decision. What is Spring Boot? Spring Boot is a Java-based framework built on top of the Spring ecosystem. It simplifies the traditionally complex setup of Spring applications by offering auto-configuration, embedded servers, and production-ready defaults out of the box. It’s widely used in banking, insurance, healthcare, and large-scale enterprise systems where reliability and structure matter most. Since Spring Boot is built on Java, having a strong foundation in Java can make it easier to understand its architecture and development concepts. You can explore Akira Global Technologies’ Java Full Stack Course to build those fundamentals and develop broader full-stack skills. Key traits: What is Node.js? Node.js is a JavaScript runtime built on Chrome’s V8 engine that lets developers run JavaScript outside the browser. Paired with frameworks like Express.js, NestJS, or Fastify, it’s the go-to choice for startups, real-time applications, and teams that want to use one language across the entire stack. Key traits: Spring Boot vs Node.js: Head-to-Head Comparison Factor Spring Boot Node.js Language Java / Kotlin JavaScript / TypeScript Performance Excellent for CPU-heavy, multithreaded tasks Excellent for I/O-heavy, real-time tasks Learning Curve Steeper (OOP, annotations, boilerplate) Gentler, especially for JS developers Scalability Vertical + horizontal, strong for large systems Horizontal scaling, great for microservices Ecosystem Mature, enterprise-grade Huge, fast-moving, npm-driven Best For Enterprise apps, banking, complex business logic Real-time apps, APIs, startups, MVPs Concurrency Model Thread-per-request Event loop, non-blocking Job Market Strong in large enterprises and legacy systems Strong in startups and product companies Performance and Scalability When comparing Spring Boot vs Node.js for performance and scalability, the right choice depends largely on the type of workload your application needs to handle. Node.js shines in I/O-bound applications – chat apps, streaming services, APIs that make frequent database or network calls – because its non-blocking event loop can handle thousands of concurrent connections efficiently. Spring Boot performs better in CPU-bound, computation-heavy workloads thanks to Java’s multithreading capabilities and the JVM’s mature optimisation (JIT compilation, garbage collection tuning). This is why it remains the backbone of high-volume enterprise systems. Learning Curve If you already know JavaScript, Node.js will feel like a natural extension – you can build a working API in an afternoon. Spring Boot has more upfront investment: understanding Java syntax, object-oriented principles, dependency injection, and annotations takes longer, but it also instills disciplined software design habits that pay off in large codebases. Job Market and Career Opportunities Both skill sets are in high demand – the “better” choice often depends on the industry you want to work in. Which One Should You Learn First? Choose Spring Boot if you: Choose Node.js if you: If you’re just starting out and unsure of your career direction, Node.js generally offers a faster path to building and deploying real projects. If you’re aiming for enterprise or backend-specialist roles, Spring Boot is a stronger long-term investment. Conclusion There’s no universal “winner” – Spring Boot and Node.js solve backend problems differently and excel in different environments. Many experienced developers eventually learn both, using Node.js for rapid, lightweight services and Spring Boot for robust, enterprise-grade systems. The smartest move is to pick the one that aligns with your career goals, learn it deeply, and expand from there. Frequently Asked Questions (FAQs) 1. Is Spring Boot better than Node.js for beginners? Not necessarily. Node.js is generally easier for beginners, especially those who already know JavaScript, because it has a gentler learning curve and faster setup. Spring Boot requires understanding Java and object-oriented concepts first. 2. Which pays more, Spring Boot or Node.js developers? Salaries vary by region and company, but Spring Boot developers in large enterprises often command strong salaries due to specialized Java expertise. Node.js developers, especially full-stack ones, are also well paid, particularly at startups and product companies. 3. Can Node.js handle enterprise-level applications? Yes, with the right architecture (using TypeScript, NestJS, proper testing, and monitoring), Node.js can power enterprise applications. However, Spring Boot’s ecosystem is more battle-tested for extremely large, complex enterprise systems. 4. Do I need to know Java to learn Spring Boot? Yes, a solid understanding of Java (or Kotlin) is essential before learning Spring Boot, since the framework is built entirely on Java’s object-oriented principles and syntax. 5. Is it worth learning both Spring Boot and Node.js? Yes, many developers learn both to become more versatile. Node.js is great for quick, lightweight, real-time services, while Spring Boot is ideal for robust, enterprise-grade backend systems – knowing both broadens your career opportunities.
Docker vs Kubernetes: Key Differences Explained Simply
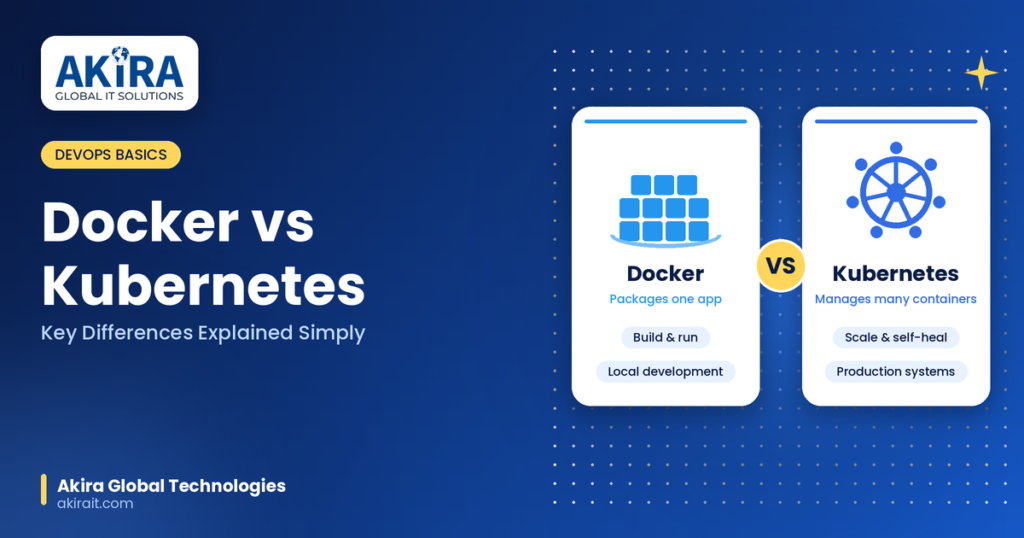
If you have started exploring a career in DevOps, you have probably run into two words that show up everywhere: Docker and Kubernetes. People often use them in the same sentence, which makes beginners assume they are competitors. They are not. Understanding Docker vs Kubernetes is actually one of the first building blocks of learning container orchestration, and it is a lot simpler than it sounds once you see how the two tools work together. In this guide, we will break down what each tool does, how they are different, when to use one over the other, and how they fit into a real DevOps career. No jargon, no assumptions, just plain English explanations for beginners, students, and working professionals thinking about a switch into tech. If you want a structured way to learn these tools hands-on, Akira Global Technologies’ DevOps training programs cover both in depth, alongside real projects you can show employers. What Is Docker? Docker is a tool that packages an application and everything it needs to run (code, libraries, settings) into a single unit called a container. Think of a container as a sealed box that carries your app plus every ingredient it depends on, so it runs the same way no matter where you open that box. Before Docker, a common developer complaint was “it works on my machine, but not on the server.” That happened because different machines had different versions of software installed. Docker solves this by keeping everything an app needs bundled together, so the app behaves identically on a laptop, a testing server, or a production server in the cloud. If you are just starting out, a simple Docker tutorial usually walks you through three steps: Docker is brilliant at packaging and running one app in one container. But real businesses rarely run just one container. They often run hundreds, sometimes across multiple servers. That is where things get complicated, and that is exactly the problem Kubernetes was built to solve. What Is Kubernetes? Kubernetes (often shortened to K8s) is a system that manages large numbers of containers for you. If Docker creates the boxes, Kubernetes is the warehouse manager deciding where each box goes, making sure none of them go missing, and replacing a box automatically if it gets damaged. For someone exploring Kubernetes for beginners, the easiest way to think about it is this: Kubernetes handles container orchestration, meaning it automatically starts, stops, scales, and monitors containers across many servers so a human does not have to do it manually. Kubernetes takes care of tasks like: None of this replaces Docker. In fact, Kubernetes usually manages containers that were built using Docker or a similar tool. They work as a team, not as rivals. Docker vs Kubernetes: The Core Difference Here is the simplest way to remember the difference. Docker is about building and running a single container. Kubernetes is about managing many containers across many machines. One packages the app, the other manages the army of packaged apps once your product grows. Comparison Table: Docker vs Kubernetes Aspect Docker Kubernetes Main Purpose Packages and runs applications in containers Manages and coordinates many containers automatically Scale Best for a single container or a small setup Built for large, multi-container, multi-server systems Scaling Apps Manual, needs extra tools for large scale Automatic scaling based on demand Self-Healing Not built in Automatically restarts failed containers Learning Curve Beginner friendly, quick to start Steeper, more concepts to learn Works Alone? Yes, for simple projects Usually manages containers created by Docker or similar tools Best For Local development, small apps, learning basics Production systems, enterprise apps, high traffic platforms Real World Analogy Imagine you run a food delivery business. Docker is like a standardized meal box. Every box contains exactly what is needed: the food, the cutlery, the napkin, the sauce packet. No matter which restaurant packs it, the box always works the same way when it reaches the customer. That consistency is exactly what Docker gives an application. Kubernetes is the delivery fleet management system. It decides how many delivery boxes need to go out based on demand, which driver takes which route, what happens if a driver’s bike breaks down (send another one immediately), and how to add more drivers during a lunch rush without anyone placing a manual phone call. The meal boxes (Docker containers) are useless at scale without a system managing the fleet (Kubernetes). And the fleet management system needs standardized boxes to manage in the first place. That is the real relationship between the two. When to Use Docker vs Kubernetes Most confusion around Docker vs Kubernetes disappears once you look at real use cases instead of definitions. Use Docker When: Use Kubernetes When: Many teams start with Docker alone. As the product grows and the number of containers increases, they introduce Kubernetes to manage that complexity. This progression is exactly what Akira Global Technologies teaches through its Kubernetes and Docker curriculum, moving learners from single-container basics to full container orchestration. Why This Matters for Your DevOps Career Container orchestration skills are consistently listed among the most in-demand DevOps skills by hiring managers. Companies do not just want someone who knows Docker commands. They want professionals who understand how containers behave at scale, how to troubleshoot failures, and how to keep systems running with minimal downtime. If you are a student or working professional considering a career in DevOps, understanding Docker and Kubernetes can help you develop skills that are widely used in modern DevOps workflows. It applies across industries, from fintech to healthcare to retail, and it is rarely tied to a single tech stack, which makes it a flexible, future-proof skill. For businesses, the same skill gap creates hiring pressure. Companies often need experienced DevOps engineers fast, which is why IT staffing and recruitment support and upskilling go hand in hand. If your organization is building internal capability instead of hiring externally, structured corporate IT training on Docker and Kubernetes can close that gap
Python for Data Science: Complete Beginner’s Roadmap 2026
Data science continues to be one of the most in demand career paths in the world, and Python remains the top choice for anyone stepping into this field. If you are wondering how to become a data scientist in 2026, this complete beginner’s roadmap will walk you through every stage of the journey, from writing your first line of Python code to building real world machine learning models. Whether you are a student, a career changer, or someone simply curious about data science, this guide breaks down exactly what to learn, in what order, and why Python is the language of choice for millions of data professionals worldwide. Why Python for Data Science in 2026 Python has held its position as the leading language for data science for over a decade, and 2026 is no exception. Here is why it continues to dominate the field. Simple and readable syntax. Python reads almost like plain English, which makes it easier for beginners to pick up compared to languages like Java or C++. Massive ecosystem of libraries. From data manipulation to deep learning, Python has a dedicated library for nearly every task a data scientist needs. Strong community support. With millions of developers using Python, finding tutorials, forums, and solutions to problems is never difficult. Integration with AI and machine learning. Python is the backbone of most modern AI tools, including TensorFlow, PyTorch, and scikit-learn, making it the natural choice as data science and artificial intelligence continue to merge. High demand in the job market. Companies across every industry, from healthcare to finance to e-commerce, are hiring Python-skilled data professionals, and this demand is expected to keep growing through 2026 and beyond. Step 1: Learn Python Programming Fundamentals Before diving into data science tools, you need a solid grip on core Python programming. If you want to build a stronger foundation in Python and explore practical application development, you can also check out Akira IT Solutions’ Python Full Stack Development Course. Focus on these fundamentals first: Spend around three to four weeks mastering these concepts through hands-on practice. Writing small programs, such as a calculator or a to-do list app, helps reinforce what you learn far better than passive reading. Step 2: Get Comfortable with Data Structures and Algorithms Basics You do not need to become a competitive programmer, but understanding basic data structures and algorithmic thinking will help you write efficient code later when working with large datasets. Focus on: This step is often skipped by beginners, but it pays off significantly when you start working with performance heavy data pipelines. Step 3: Master Python Libraries for Data Analysis Once your Python fundamentals are solid, it is time to learn the libraries that make data science possible. These four libraries form the backbone of nearly every data science project. NumPy NumPy is the foundation for numerical computing in Python. It introduces the powerful array object and allows fast mathematical operations on large datasets. Learn how to create arrays, perform element-wise operations, reshape data, and use broadcasting. Pandas Pandas is where most data scientists spend the bulk of their time. It allows you to clean, transform, and analyze structured data using DataFrames. Key skills to build here include reading data from CSV and Excel files, filtering and grouping data, handling missing values, merging datasets, and performing exploratory data analysis. Matplotlib and Seaborn Data visualization is essential for communicating insights. Matplotlib gives you full control over plots, while Seaborn builds on top of it with more attractive statistical visualizations. Learn to create bar charts, histograms, scatter plots, heatmaps, and box plots. SciPy SciPy extends NumPy with additional functionality for scientific and technical computing, including statistics, optimization, and signal processing. Give yourself about six to eight weeks to become comfortable with these libraries. Practice on real datasets from sources like Kaggle to build practical experience. Step 4: Understand Statistics and Mathematics for Data Science Data science is built on a mathematical foundation, and you do not need a PhD to grasp what matters most. Focus on these core areas. Descriptive statistics: mean, median, mode, variance, and standard deviation. Probability theory: probability distributions, conditional probability, and Bayes theorem. Inferential statistics: hypothesis testing, confidence intervals, and p-values. Linear algebra basics: vectors, matrices, and matrix operations, since these concepts underpin machine learning algorithms. Calculus basics: derivatives and gradients, which are essential for understanding how machine learning models learn. You do not need to master every equation, but understanding the intuition behind these concepts will make machine learning far less intimidating later on. Step 5: Learn Data Cleaning and Exploratory Data Analysis Real world data is messy. Studies consistently show that data scientists spend a significant portion of their time cleaning and preparing data before any modeling begins. This makes exploratory data analysis, often called EDA, one of the most valuable skills you can develop. Key skills to practice include: Work on multiple real datasets during this stage. The more variety you expose yourself to, from messy survey data to structured sales records, the more confident you will become at handling unpredictable data in the real world. Step 6: Learn SQL for Data Extraction While Python handles analysis, most real world data lives in databases, which means SQL is a non-negotiable skill for any data scientist. Learn to: Many data science interviews test SQL skills directly, so this step should not be skipped even though it is not Python specific. Step 7: Dive into Machine Learning with Scikit-learn Once your data handling skills are strong, you are ready for machine learning. Scikit-learn is the ideal starting point because of its simple and consistent interface. Begin with supervised learning algorithms such as linear regression, logistic regression, decision trees, and random forests. Then move into unsupervised learning, including k-means clustering and principal component analysis. Along the way, learn essential concepts like: Build small end to end projects here, such as predicting house prices or classifying customer churn, to apply what you learn in a practical setting. Step 8: Explore
What is Generative AI? A Simple Guide for Non-Tech Professionals
If you have heard the term “generative AI” thrown around in meetings, news articles, or LinkedIn posts and felt a little lost, you are not alone. Most explanations of this technology are written by engineers, for engineers, full of technical terms that make sense to programmers but leave everyone else more confused than before. This guide is different. It is written specifically for marketers, HR professionals, accountants, teachers, small business owners, and anyone else who wants to understand generative AI without needing a computer science degree. By the end, you will know what it is, how it works in plain terms, and how you might use it in your own job. What is Generative AI, Really? Generative AI refers to computer programs that can create new content instead of just analyzing existing information. Traditional software follows fixed rules to complete tasks. A calculator adds numbers. A spreadsheet sorts data. Generative AI does something different: it produces original text, images, audio, video, or code based on a prompt you give it. Think of it like a very well read assistant who has studied millions of books, articles, images, and conversations, and can now use that knowledge to write an email, draft a report, design an image, or answer a question in a natural, human sounding way. Tools like ChatGPT, Claude, Google Gemini, and Midjourney are all examples of generative AI. When you type a question or instruction into one of these tools, it generates a fresh response rather than pulling up a pre-written answer from a database. How Does Generative AI Actually Work? You do not need to understand the math behind generative AI to use it effectively, but a basic idea of how it works will help you use it more confidently. For those interested in understanding AI concepts in greater depth, an AI and Machine Learning course can provide a more structured learning path. 1. It Learns From Massive Amounts of Data Generative AI models are trained on huge datasets, often including books, websites, articles, and other publicly available text or images. During training, the model learns patterns: how sentences are typically structured, how ideas connect, what a cat usually looks like in a photo, and so on. 2. It Predicts What Comes Next At its core, a generative AI model like ChatGPT works by predicting the most likely next word in a sentence, one word at a time, based on everything it has learned. It does this so quickly and so well that the output reads like it was written by a person. 3. It Responds to Your Instructions When you give the AI a prompt, such as “write a two paragraph summary of this report,” it uses its training to generate a response that fits your request. The quality of what you get back often depends on how clearly you explain what you want, which is why learning to write good prompts is a useful skill. Why Should Non-Tech Professionals Care? You do not need to be a developer to benefit from generative AI. In fact, some of the biggest productivity gains are happening in non-technical roles. Here are a few reasons this matters to you. It saves time on repetitive writing tasks. Drafting emails, meeting summaries, job descriptions, or social media captions can take up a surprising chunk of the workday. Generative AI can produce a solid first draft in seconds, which you can then edit and personalize. It helps you think through problems. You can use it as a brainstorming partner. Ask it to list pros and cons, suggest alternative approaches to a project, or explain a concept you are unfamiliar with. It levels the playing field for smaller teams. A small business without a dedicated design or content team can use generative AI to create marketing copy, basic graphics, or presentation outlines that once required outside help. It is becoming part of everyday software. Many tools people already use, including Microsoft Office, Google Workspace, and Slack, are adding generative AI features directly into their products. Understanding the basics now will make those features easier to adopt later. Practical Ways to Use Generative AI at Work Here are some real world examples of how professionals across industries are already using generative AI tools. The common thread here is that generative AI works best as a starting point. It handles the first draft or the repetitive groundwork, and you bring the judgment, expertise, and final polish. Common Misconceptions About Generative AI Since this technology is relatively new, a few myths tend to circulate. Clearing these up can help you use AI more effectively and avoid frustration. Myth: It always gets facts right. Generative AI can sometimes produce information that sounds confident but is inaccurate, a problem often called “hallucination.” Always double check important facts, figures, or claims before relying on them. Myth: It will replace your job. In most cases, generative AI is better understood as a tool that changes how work gets done rather than one that eliminates the need for human judgment, creativity, and oversight. Myth: You need technical skills to use it. Most generative AI tools are designed with simple, conversational interfaces. If you can type a sentence, you can use them. Myth: The output is always ready to use as is. AI generated content usually needs some editing to match your voice, brand, or specific context. Treat it as a helpful draft, not a finished product. Getting Started With Generative AI If you are new to this technology, start small. You can also explore a Generative AI Training Program to build a stronger understanding of AI tools, prompting, and practical applications. Pick one repetitive task in your workday, such as writing meeting summaries or drafting routine emails, and try using a generative AI tool for a week. Pay attention to what works well and what needs more editing on your part. Over time, you will develop a feel for how to phrase your requests to get better results, a skill often